Monitoring the Monitor: How Observability Infrastructure Can Quietly Become Your Most Complex System

Photo by Photo by Kevin Ache on Unsplash on Unsplash
There is a particular irony that surfaces in mature engineering organizations: the systems built to provide clarity about software behavior eventually become the systems that are least understood. Dashboards multiply. Alert channels fragment across Slack, PagerDuty, and email. A logging pipeline that started as a single Elasticsearch cluster has grown into a multi-region, multi-tenant data platform with its own on-call rotation.
At some point, the observability layer stopped being a diagnostic tool and became a product in its own right — one that nobody formally decided to build.
This is the observability paradox. The more instrumentation an organization adds in pursuit of visibility, the more operational surface area it creates. Left unchecked, that surface area can rival or exceed the complexity of the application being monitored.
How Observability Sprawl Begins
Observability sprawl rarely begins with a single bad decision. It accumulates through a series of individually reasonable ones.
A team adds distributed tracing after a difficult incident. Another team instruments a new microservice with a different APM vendor because it integrates more cleanly with their language runtime. A platform engineer stands up a Prometheus instance for infrastructure metrics, while the application team is already shipping logs to a managed SaaS provider. Someone builds a custom alerting rule for a one-time edge case and never removes it.
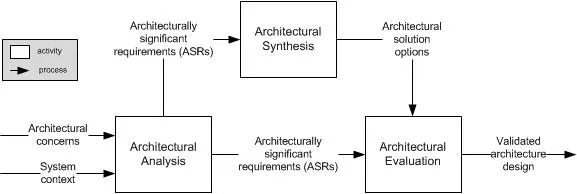
None of these decisions are wrong in isolation. The problem is the absence of a governing architecture. Without one, observability becomes additive by default — each new concern prompts a new tool, a new data source, or a new dashboard — and subtractive by exception, meaning things are rarely removed.
The result is an environment where the cost of maintaining the monitoring stack — in compute, licensing, cognitive overhead, and engineering time — begins to outweigh the diagnostic value it delivers.
Recognizing the Signals of Over-Instrumentation
Before any remediation is possible, teams need to honestly assess whether their observability infrastructure has crossed into counterproductive territory. Several indicators are worth examining.
Alert fatigue is chronic, not episodic. If engineers have developed a habit of silencing alerts without investigating them, the signal-to-noise ratio in the alerting system has broken down. This is not a tuning problem — it is a structural one.
Dashboards exist but are not consulted. A dashboard that no one opens during an incident is not a diagnostic resource; it is operational theater. The existence of a visualization does not imply that it carries meaning for the people who need it.
Onboarding to the monitoring stack takes longer than onboarding to the application. This is a useful litmus test. If a new engineer can understand the core application architecture in a week but needs three weeks to navigate the observability toolchain, the observability layer has become its own domain of expertise — and a barrier rather than an enabler.
Incident post-mortems reveal that the data needed was unavailable. Paradoxically, sprawling observability systems often fail at the moment they are needed most. When everything is instrumented, finding the relevant signal during a high-pressure incident can be harder than it would be with a leaner, more deliberate setup.
A Decision Framework for What Deserves Observation
The goal is not minimal observability — it is purposeful observability. That distinction matters. The question to ask of every metric, log stream, trace, and alert is not "could this be useful?" but "has this proven useful, and at what operational cost?"
A practical framework involves three filters.
Filter one: Does this signal map to a user-facing outcome? Metrics that reflect latency, error rates, and availability for real users carry clear diagnostic value. Metrics that reflect internal implementation details — queue depths for internal async jobs, memory utilization on non-critical workers — should be evaluated more critically. They may belong in the system, but they should not occupy the same priority tier as signals that directly affect the user experience.
Filter two: Is there a defined response to this signal? Every alert should have a documented, practiced response. If a team cannot articulate what they would do when an alert fires, the alert is informational at best and distracting at worst. Informational signals belong in dashboards reviewed during planned review cycles, not in on-call alert channels.
Filter three: What is the maintenance cost over a twelve-month horizon? This is the filter most teams skip. A custom metric that requires a dedicated pipeline, a schema migration, and periodic recalibration is not free — even if the raw data ingestion cost appears low. Engineering time spent maintaining instrumentation is time not spent on the application. That trade-off should be made explicitly, not by default.
Architectural Principles for Sustainable Observability
Once a team has audited its existing instrumentation against these filters, several architectural principles can prevent sprawl from re-accumulating.
Establish observability tiers. Not every service requires the same depth of instrumentation. Critical revenue-generating paths warrant comprehensive tracing, structured logging, and granular alerting. Internal tooling and low-traffic auxiliary services may need only basic health checks and error-rate tracking. Formalizing these tiers prevents the implicit assumption that all services should be instrumented equally.
Treat the observability stack as a product with a roadmap. This means ownership, deprecation policies, and regular reviews. Someone on the team — or a designated platform function — should be responsible for evaluating whether existing instrumentation continues to justify its cost. Without explicit ownership, the observability stack grows indefinitely.
Standardize the instrumentation interface, not the tooling. Mandating a single observability vendor across all services often creates more friction than it resolves, particularly in polyglot environments. A more durable approach is to standardize the semantic conventions — how events are named, how trace context is propagated, how severity levels are defined — while allowing some flexibility in the underlying tooling. This preserves interoperability without forcing architectural uniformity where it does not belong.
Build for investigation, not for coverage. The instinct behind over-instrumentation is often the desire to have data available for any possible future incident. This is an understandable impulse, but it optimizes for coverage rather than for the speed and clarity of actual investigation. A smaller set of high-quality, well-structured signals — ones that engineers have practiced interpreting — will outperform a comprehensive but unwieldy dataset in a real incident scenario.
The Strategic Case for Restraint
Observability is not a feature you add to a system — it is a discipline you apply to one. Like any discipline, it requires judgment about when more is not better.
Web professionals building or inheriting monitoring infrastructure should approach it with the same architectural rigor applied to the systems it serves. That means resisting the gravitational pull of "just add another metric" and instead asking whether each addition earns its place through demonstrated diagnostic value.
The teams that manage this well do not have the most comprehensive monitoring stacks. They have the most useful ones — and they can tell the difference.