Architecting for Reality: Why Over-Engineering Is Quietly Bankrupting Your Codebase
Photo: U.S. Army 1BCT-4ID by 1st Lt. Jonathan Sauls, Public domain, via Wikimedia Commons
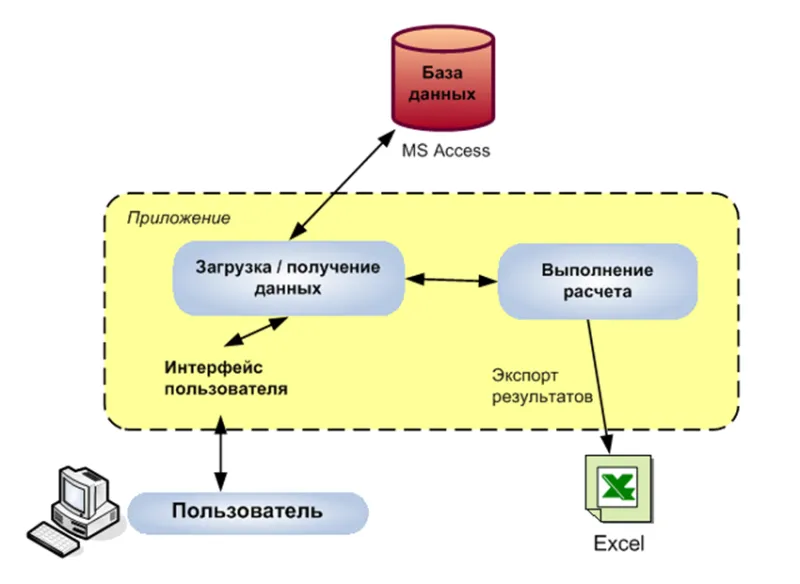
There is a particular kind of pride that comes with drawing a sophisticated architecture diagram. Boxes connected by arrows, service boundaries neatly defined, caching layers stacked three deep. It looks professional. It signals competence. And in many organizations, it quietly becomes the most expensive decision the engineering team ever makes.
Over-engineering is not a failure of ambition. It is, more often, a failure of timing. Web professionals who have spent years navigating growth crises understandably want to prevent the next one before it arrives. But the instinct to build for tomorrow — before tomorrow's requirements are even legible — carries costs that rarely appear on a project estimate.
The True Price Tag of Premature Complexity
Technical debt is most commonly associated with shortcuts: quick fixes, skipped tests, copy-pasted logic. But there is a subtler and arguably more damaging form of debt that accumulates when systems are made more complex than the problem demands.
Consider a mid-sized e-commerce platform that adopts an event-driven microservices architecture at launch because the founders believe they will be competing with Amazon within three years. The engineering team now maintains a distributed message queue, multiple independently deployed services, and an observability stack that requires its own dedicated tooling. When a junior developer needs to trace a single checkout bug, they must navigate six services and interpret asynchronous event logs.
The system was built for a scale that never materialized. Meanwhile, every new hire requires weeks of onboarding just to understand the infrastructure. Every feature addition touches three services instead of one. Deployment pipelines grow brittle. Cognitive overhead compounds.
Research from Google's DevOps Research and Assessment (DORA) program consistently finds that organizational performance correlates with deployment frequency and lead time for changes — metrics that over-engineered systems directly impede. The architecture meant to support growth actively prevents it.
Metrics That Reveal Whether You Actually Need That Scale
Before adding a caching layer, a message broker, or a distributed data store, web professionals should interrogate the actual numbers driving the decision. The following metrics provide an honest picture of current and near-term load:
Concurrent user baseline and peak ratio. If your application serves 200 concurrent users at peak and your team is designing for 50,000, ask what evidence supports that projection. Is it grounded in sales pipeline data, historical growth rates, or optimism?
Request latency under real load. Before introducing Redis, measure whether your database is actually the bottleneck. Tools like k6 or Apache JMeter can simulate realistic traffic against a staging environment and surface where latency genuinely originates.
Deployment frequency and team size. Microservices architectures yield meaningful benefits when multiple autonomous teams need to ship independently without coordination overhead. A team of four engineers deploying once a week does not meet that threshold.
Infrastructure cost per transaction. When scalability investments are made early, they often sit idle. Calculating cost per transaction across environments reveals whether architectural complexity is producing proportional efficiency gains.
If the numbers do not justify the architecture, the architecture is a liability.
The 'Build for Tomorrow' Mentality Under Scrutiny
The cultural pressure to over-engineer is real and worth naming directly. Conference talks celebrate ambitious systems. Job postings reward candidates who have worked at scale. Architecture reviews sometimes penalize simplicity as naivety rather than recognizing it as discipline.
This environment produces what might be called speculative architecture — design decisions justified not by current or demonstrable future requirements, but by the possibility of requirements that may never arrive. Speculative architecture is not inherently reckless, but it requires honest accounting.
The question is not whether your system might someday need to handle ten times its current load. The question is: what is the probability of that scenario within a defined time horizon, and what is the cost of waiting to address it then versus building for it now?
In most cases, a well-structured monolith that can be refactored into services when genuine scale demands it will outperform a premature distributed system — both in delivery speed and in total maintenance cost.
A Framework for Distinguishing Prudent Planning from Premature Optimization
Not every forward-looking architectural decision is over-engineering. The distinction lies in whether the complexity introduced today creates proportional, near-term value or defers value indefinitely.
Apply this three-part assessment before committing to a scalability investment:
1. Define the triggering threshold. Rather than designing for hypothetical scale, identify the specific metric that would justify the architectural change. For example: "We will introduce a dedicated caching layer when database query latency exceeds 200ms under a sustained load of 1,000 concurrent users." This converts a speculative decision into a conditional one.
2. Estimate the refactoring cost. If you build a simpler system now and scale it later, what is the realistic cost of that migration? In many cases — particularly for startups and growing SMBs — the cost of future refactoring is lower than the ongoing cost of maintaining premature complexity. Run the numbers explicitly.
3. Assess reversibility. Architectural decisions vary in how easily they can be undone. Choosing a relational database over a document store is relatively reversible. Decomposing a monolith into 15 microservices is not. Weight your tolerance for complexity against the reversibility of the choice.
Simplicity as a Strategic Asset
The most resilient web architectures are not necessarily the most sophisticated ones. They are the ones that the team can reason about clearly, modify confidently, and operate without specialized tribal knowledge.
Simplicity is not a compromise. It is a deliberate architectural decision that preserves optionality, reduces onboarding friction, and keeps delivery velocity high during the periods when it matters most — which is typically early in a product's lifecycle, before product-market fit is confirmed and before team size justifies distributed complexity.
The best architects know how to plan for scale. The most effective ones also know when not to.
Before your next architecture review, ask the team a direct question: are we solving a problem we have, or one we are afraid of having? The answer will tell you more than any diagram.